JavaScript SEO: Rendering and Indexing Basics
JavaScript SEO makes sure that the content, links, and metadata of a JavaScript-based website are reachable for search engines even though they only come into being in the browser. Google can execute JavaScript. Whether a page is indexed completely, correctly, and on time, however, depends on three factors: how the page is rendered, which signals are already in the first HTML, and whether errors such as soft 404s or blocked resources lurk in the code. This guide explains how Google processes the pages, compares the rendering strategies, names the most common sources of error, and shows how to check after a relaunch or a sudden ranking loss whether JavaScript is the cause.
Making JavaScript pages visible to Google
SEYBOLD ONE combines technical SEO with data-driven strategies to specifically check rendering problems and possible causes of ranking losses.
Get a free consultationWhat JavaScript SEO covers
Google itself describes JavaScript SEO as the optimization of JavaScript-powered web applications for Google Search and dedicates its own documentation to the topic, the JavaScript SEO basics. The discipline is a sub-area of technical SEO. It mainly concerns websites based on frameworks such as React, Vue, or Angular, single-page applications, shops with product lists loaded on the client side, and all pages whose main content, internal linking, or meta information is created or changed by JavaScript.
At its core it comes down to one question: does what Googlebot sees after rendering match what a user sees in the browser? If headings, product texts, canonical tags, or links only appear after an interaction, an API call, or a cookie check, a gap arises between the user's and the crawler's view. This very gap is the cause of most JavaScript SEO problems.
How Google processes JavaScript pages
According to Search Central, Google processes JavaScript pages in three phases: crawling, rendering, and indexing. Anyone who understands this sequence quickly sees where a page gets stuck.
- Crawling: Googlebot first checks the robots.txt, fetches the allowed URL, and extracts further URLs from the
hrefattributes of HTML links. Links that only work viaonclickhandlers or JavaScript routing without a real<a href>are not reliably discovered in this phase. - Rendering: Pages with HTTP status code 200 are placed in a queue for rendering. The Web Rendering Service (WRS) executes the JavaScript with a current Chromium and produces the rendered HTML. Pages with an error status or a noindex signal in the initial HTML are generally not rendered at all.
- Indexing: Google uses the rendered HTML for indexing and also extracts the links that only came into being through JavaScript. These then go back into crawling.
The frequently invoked “second wave” of indexing, in which weeks are supposed to lie between crawling and rendering, is outdated in this form. An analysis by Vercel on how Google handles JavaScript covering more than 100,000 Googlebot fetches found that all indexable HTML pages with status code 200 were fully rendered and that the median rendering delay was around ten seconds. Individual pages, however, waited considerably longer. For websites with hundreds of thousands of URLs, frequently changing content, or a tight crawl budget, this delay remains relevant because new or changed content arrives in the index later.
Handling meta robots instructions is particularly critical. Google makes clear in its documentation that with a noindex in the original HTML it may skip rendering and JavaScript execution. A script that is supposed to remove a noindex afterward then has no effect. Indexing-relevant signals such as robots instructions, canonical, and status code therefore belong in the HTML delivered by the server or in the HTTP header, for example via the X-Robots-Tag.
In the SEO guide for web developers, Google sums up the situation soberly: JavaScript can in principle be executed, but the design has to take into account the particularities and limitations for crawling and rendering. In addition, Google is not the only consumer of your content. Whether other crawlers, such as those of AI answer systems, execute JavaScript is not guaranteed. HTML delivered by the server is therefore the more robust basis for visibility in classic search and in AI answers.
Rendering strategies compared
The choice of rendering strategy decides how much work lies with the crawler and how early the actual content appears in the HTML. According to the explanations by web.dev on JavaScript and Google Search, the rendering strategy influences both performance and robustness; server rendering and pre-rendering make the first HTML content available earlier.
| Strategy | Where the content is created | Advantages for SEO | Risks | Suitable for |
|---|---|---|---|---|
| Client-side rendering (CSR) | In the browser, by JavaScript | Low server load, app-like operation | Content missing in the initial HTML, dependent on rendering, resources, and APIs | Logged-in areas, dashboards, tools without search relevance |
| Server-side rendering (SSR) | On the server, per request | Complete HTML available immediately, unambiguous signals | Higher server load, more complex infrastructure | Shops, category pages, editorial content |
| Static pre-rendering (SSG) | At build time, as finished HTML files | Very fast, stable, easy to cache | Updating requires a new build | Guides, landing pages, documentation |
| Hybrid with hydration | Server delivers HTML, browser takes over afterward | Combines indexable HTML and interactivity | Deviations between server and client output | Most modern framework projects |
| Dynamic rendering | Server detects crawlers and delivers a pre-rendered version to them | Short-term relief for legacy systems | Maintaining two versions, error-prone, according to Google only a workaround | Transition phase until migration |
Client-side rendering
With client-side rendering, the browser loads a largely empty HTML shell and a JavaScript bundle that creates the content during execution. For users this is often unproblematic; for search engines it means: the content only exists after rendering. Every error in this chain, a blocked script, a slow API, a timeout, or a code error, leads to Google indexing an empty or incomplete page. CSR is not bad for SEO per se, but it shifts the risk entirely onto the rendering step.
Server-side rendering and pre-rendering
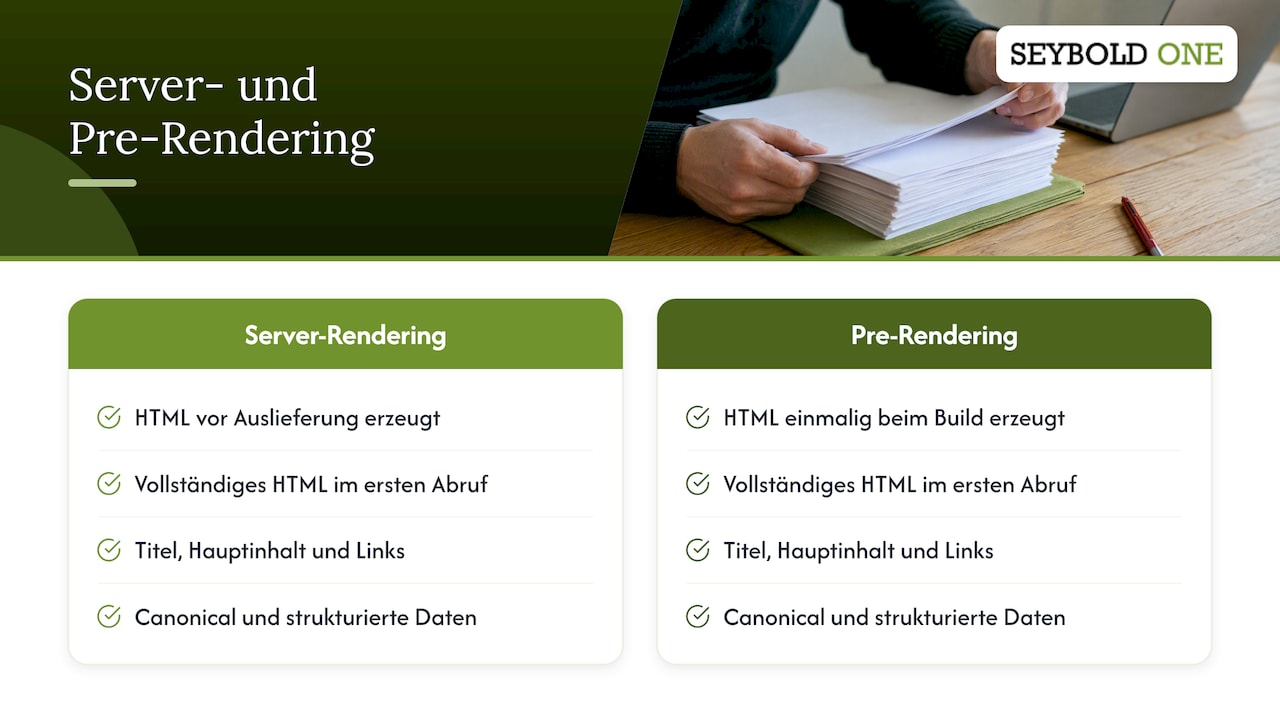
With server-side rendering, the server produces the complete HTML before it is delivered. Title, main content, internal links, canonical, and structured data are thus already in the first fetch. Static pre-rendering pursues the same goal but produces the HTML once at build time. Modern frameworks offer both variants and allow combining them per page type: guide pages static, product pages with server rendering, the shopping cart on the client side. For search-relevant pages we recommend this route as the standard.
Dynamic rendering: a workaround
With dynamic rendering, the server detects crawlers by user agent and delivers them a server-rendered version while users receive the client-side version. Google explicitly describes dynamic rendering as a workaround and not as a long-term solution, because it causes additional complexity and resource requirements. In practice we regularly see with such setups that the crawler version is outdated, incomplete, or faulty after a deployment without anyone noticing, because users see the correct version. Anyone who still uses dynamic rendering should plan the switch to SSR or pre-rendering.
Typical JavaScript SEO problems
In its guide to fixing search-related JavaScript problems, Google lists a number of recurring error patterns. The following overview arranges them by symptom and solution.
| Problem | Typical symptom | Solution |
|---|---|---|
| Soft 404 in single-page apps | Error pages return HTTP 200 and end up in the index | Send a real 404 status on the server or redirect via JavaScript to a 404 URL or set noindex |
URL fragments (#/product) | Subpages are not recognized as separate URLs | Use the History API with clean paths |
| Dependence on stored state | Content only appears with a cookie, LocalStorage, or login | Deliver content statelessly, since the WRS doesn't keep state between fetches |
| Unsupported APIs or permissions | Content stays empty because, for example, location permission is expected | Use feature detection with a fallback |
| Outdated JS and CSS resources in the cache | Rendered page breaks after a deployment | Content fingerprinting in file names, such as main.2bb85551.js |
| Web components without visible content | Shadow DOM content is missing in the rendered HTML | Bring content into the light DOM via slots and check the rendered HTML |
Links without href | Subpages are not discovered | Use real <a href> links |
| Loading only on scroll or click | Products or paragraphs are missing in the index | Load content without interaction, offer pagination with its own URLs |
Two points deserve special attention. First, soft 404s: because the client-side error handling of a single-page app often returns status code 200, Google can index hundreds of empty error pages and thereby burden crawl budget and the quality assessment of the domain. Second, lazily loaded content: Googlebot doesn't scroll like a human and doesn't click “Load more” buttons. For category pages and lists it also applies that every page needs its own, linked URL, as explained in the guide to pagination in SEO.
Another frequently overlooked problem is the blocking of resources. If JavaScript files, CSS, or API endpoints are blocked via robots.txt, the WRS can't build the page completely. The result is a rendered page that looks different to Google than to users, without an error being recognizable in the source code.
How to check what Google actually sees
The most important principle is: check instead of assume. The source code in the browser shows the initial HTML, the developer tool shows the DOM in your browser, but neither necessarily shows what Google rendered. Proceed in this order:
- URL Inspection tool in Search Console: For a representative URL per page type, run the live test and open the rendered HTML. Check whether main content, headings, internal links, canonical, and structured data are present.
- Loaded resources and JavaScript console: In the same test, Google shows which resources could not be loaded and which JavaScript exceptions occurred. Blocked or faulty scripts are immediately visible here.
- Rich Results Test: The tool also renders with the WRS and is suitable if you have no Search Console access to the domain.
- Comparing initial HTML and rendered HTML: A crawler with and without JavaScript rendering shows which content and links arise exclusively through JavaScript. The larger this difference, the higher the risk.
- Crawl stats report: It shows the activity of Googlebot and the WRS. Google points out that client-side analytics tools may not capture this activity completely or accurately; server log files give the more accurate picture.
- Page indexing report: Accumulations of “Soft 404”, “Crawled – currently not indexed”, or “Duplicate, Google chose different canonical than user” often point to rendering or signal problems.
Diagnosis after a relaunch or ranking loss
Many JavaScript SEO problems don't become visible when a website is built but at the relaunch: a new front-end framework, a headless CMS, or a theme switch suddenly moves content that used to be in the HTML into client-side components. Rankings then don't fall immediately but gradually, as soon as Google has rendered and re-evaluated the new versions. The following approach has proven useful for the diagnosis:
- Narrow down the time: Match the start of the decline in Search Console against deployments, relaunch dates, and Google updates. A drop that begins exactly with a release points to a technical cause.
- Identify the affected page types: Are only category pages, only product pages, or only certain directories losing? A pattern by page type almost always points to a template or a component.
- Compare old and new: Set the initial HTML and the rendered HTML of the old version (from archives or crawls before the relaunch) against the new version: amount of text, headings, internal links, canonical, meta robots, structured data.
- Check signals in the initial HTML: Is a
noindexfrom the staging environment still in the template? Does the canonical point to a wrong domain? Is the status code for non-existent URLs set correctly? - Recount internal linking: If navigation, filters, or breadcrumbs work without a real
hrefafter the relaunch, deeper pages lose their internal linking. This often explains why subpages gradually drop out of the index. - Evaluate log files: Server logs show which URLs and resources Googlebot actually fetches, whether API endpoints are reachable, and whether crawl frequency has collapsed after the relaunch.
- Correct, prioritize, validate: Fix errors with a large reach first, meaning templates and global components, test the correction in the URL Inspection tool, and request indexing for central URLs. Depending on the scope, recovery stretches over weeks because Google has to crawl and render the affected pages again.
Anyone who runs through these steps on a staging environment before go-live prevents most losses from the start. A structured overview of the basic checks is provided by our SEO basics checklist.
Best practices for development and SEO
Google's recommendations and our project experience yield rules that development and SEO teams should record together, ideally as acceptance criteria in every release:
- Deliver search-relevant content on the server side: Main content, title, meta description, canonical, and structured data are in the first HTML fetch.
- Send meaningful HTTP status codes: 404 for non-existent pages, 301 for permanent redirects, never an error page with 200.
- History API instead of fragments: Every indexable view has its own, descriptive URL.
- Use real links: Navigation, pagination, and filters that are meant to be indexed work with
<a href>. - No dependence on state or permissions: Content loads without cookie consent, login, LocalStorage, or location permission.
- Feature detection with a fallback: If a browser API is missing, the content is output anyway.
- Content fingerprinting for resources: Versioned file names prevent the WRS from using outdated scripts after a deployment.
- Don't block resources: JavaScript, CSS, and required API endpoints remain reachable for Googlebot.
- Test rendered HTML regularly: After every larger release, check at least one URL per page type in the URL Inspection tool.
Our perspective on JavaScript SEO
In more than 25 years of visibility management, we have learned that JavaScript is rarely the actual problem. The problem is the assumption that Google will already see what the user sees. In ranking losses after a relaunch, we keep finding the same patterns in forensic analyses: content that now only arises on the client side, internal links without href, staging signals in the template, or error pages with status code 200. None of these patterns is visible in the browser, and that is why they often go undiscovered for months.
Our approach is data-driven: we compare initial HTML, rendered HTML, and log files instead of relying on individual tool warnings. And we recommend that companies treat rendering not as a decision of development alone but as a visibility decision. Anyone who chooses an architecture today decides not only on indexing at Google but also on whether answer systems of AI search can read the content at all. HTML delivered on the server side and cleanly structured is therefore for us not a technical detail but the basis of every sustainable visibility.
Support with JavaScript SEO
If you have lost visibility after a relaunch or a framework switch, or want to secure a rebuild, we offer suitable services. A technical audit costs €1,500 to €3,500, a forensic audit for root cause analysis of sudden ranking losses €1,500 to €5,500, and relaunch safeguarding starts from €1,500. Anyone who wants to bring the knowledge into their own team finds an entry in our Technical SEO workshop from €500. You will find all packages and prices in our overview How much does SEO cost? As a first step, you can request a free initial analysis.
Frequently asked questions about JavaScript SEO
Can Google read JavaScript at all?
Yes. Google renders pages with a current Chromium and indexes the rendered HTML. This only applies, however, if rendering succeeds without errors, all required resources are reachable, and there is no noindex in the initial HTML. Whether other search engines and AI crawlers execute JavaScript just as well is not assured.
Is server-side rendering always better for SEO?
For search-relevant pages, server-side rendering or static pre-rendering is the most robust choice, because content and signals are in the HTML immediately. For logged-in areas, configurators, or dashboards without search relevance, client-side rendering is unproblematic. Most projects do best with a hybrid solution per page type.
Should I still use dynamic rendering?
Google describes dynamic rendering as a workaround and not as a long-term solution. For legacy systems it can bridge a transition phase, but it requires maintaining two versions and is error-prone. Plan the switch to SSR or pre-rendering.
How do I recognize that JavaScript is costing me rankings?
Typical hints are a decline that coincides with a release, rising numbers for “Soft 404” or “Crawled – currently not indexed”, and missing content or links in the rendered HTML of the URL Inspection tool. The proof comes from comparing initial HTML, rendered HTML, and server log files.
Sources
- Understand JavaScript SEO Basics, Google Search Central
- SEO guide for web developers, Google Search Central
- Fix Search-Related JavaScript Problems, Google Search Central
- Dynamic rendering as a workaround, Google Search Central
- Getting your JavaScript and Google Search aligned, web.dev
- How Google handles JavaScript throughout the indexing process, Vercel